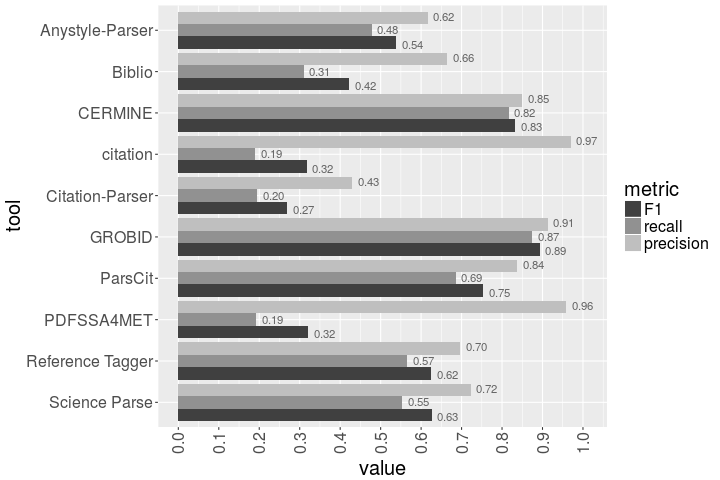
The results of the comparison of 10 open-source bibliographic reference parsers

Machine Learning vs. Rules and Out-of-the-Box vs. Retrained: An Evaluation of Open-Source Bibliographic Reference and Citation Parsers

Our paper “Machine Learning vs. Rules and Out-of-the-Box vs. Retrained: An Evaluation of Open-Source Bibliographic Reference and Citation Parsers” got recently accepted and will be presented at Joint Conference on Digital Libraries 2018. Abstract: Bibliographic reference parsing refers to extracting machine-readable metadata, such as the names of the authors, the Read more…

The workflow of author contributions extraction

Who Did What? Identifying Author Contributions in Biomedical Publications using Naïve Bayes

Our paper “Who Did What? Identifying Author Contributions in Biomedical Publications using Naïve Bayes” got recently accepted and will be presented at Joint Conference on Digital Libraries 2018. Abstract: Creating scientific publications is a complex process. It is composed of a number of different activities, such as designing the experiments, Read more…

RARD I: The Related-Article Recommender-System Dataset

RARD: The Related-Article Recommendation Dataset

We are proud to announce the release of ‘RARD’, the related-article recommendation dataset from the digital library Sowiport and the recommendation-as-a-service provider Mr. DLib. The dataset contains information about 57.4 million recommendations that were displayed to the users of Sowiport. Information includes details on which recommendation approaches were used (e.g. content-based Read more…

Several new publications: Mr. DLib, Lessons Learned, Choice Overload, Bibliometrics (Mendeley Readership Statistics), Apache Lucene, CC-IDF, TF-IDuF

In the past few weeks, we published (or received acceptance notices for) a number of papers related to Mr. DLib, research-paper recommender systems, and recommendations-as-a-service. Many of them were written during our time at the NII or in collaboration with the NII. Here is the list of publications: Beel, Joeran, Bela Gipp, Read more…

Paper accepted at ISI conference in Berlin: “Stereotype and Most-Popular Recommendations in the Digital Library Sowiport”

Our paper titled “Stereotype and Most-Popular Recommendations in the Digital Library Sowiport” is accepted for publication at the 15th International Symposium on Information Science (ISI) in Berlin. Abstract: Stereotype and most-popular recommendations are widely neglected in the research-paper recommender-system and digital-library community. In other domains such as movie recommendations and hotel Read more…

Enhanced re-ranking in our recommender system based on Mendeley’s readership statistics

Content-based filtering recommendations suffer from the problem that no human quality assessments are taken into account. This means a poorly written paper ppoor would be considered equally relevant for a given input paper pinput as high-quality paper pquality if pquality and ppoor contain the same words. We elevate for this problem by using Mendeley’s readership data Read more…

Howto: Import references from webpages (e.g. PubMed, IEEE, ACM, …)

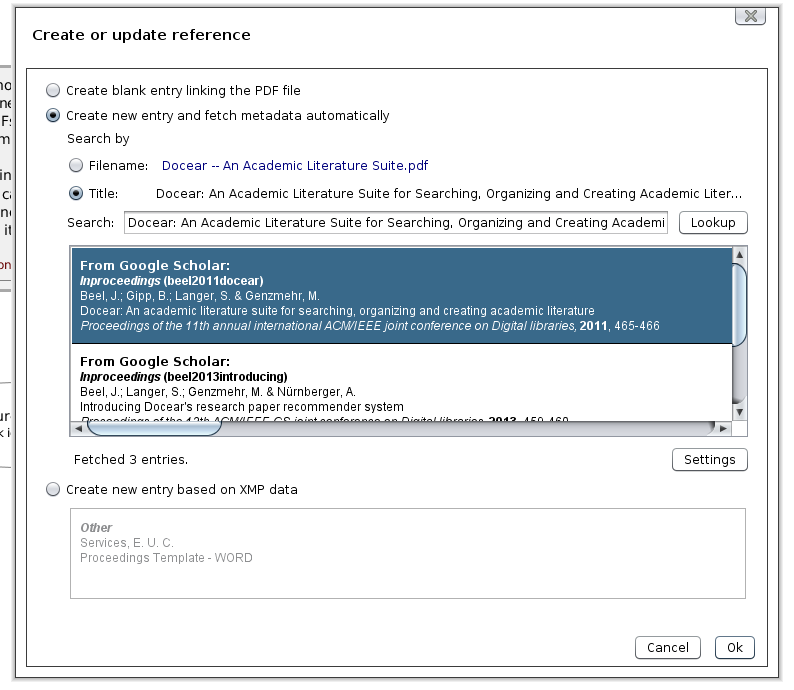
Compared to several other reference managers, Docear lacks a feature to directly import references from the Web. For instance, if you visit the detail page of a research article on a publisher’s website, you might wish to directly import the bibliographic data of that article to Docear. Many publishers offer export options for reference managers such as Endnote, RefWorks, or Zotero. So, how do you do it with Docear?

Fortunately, Docear uses the BibTeX format to store references. BibTeX is a de-facto standard for references that is supported by almost any publisher and any reference manager. So, read on to learn how to import bibliographic data from web-pages in two steps!

(more…)

Docear 1.1.1 Beta with Academic Search Feature

As you may know, Docear features a recommender system for academic literature. To find out which papers you might be interested in, the recommender system parses your mind maps and compares them to our digital library with currently about 1.8 million academic articles. While this is helpful and might point you to papers relevant for your general research goals, you will sometimes have to find information on a specific topic and hence search directly.

Based on our knowledge about recommender systems and some user requests, we decided to implement a direct search feature on our digital library. I am very grateful to Keystone, who supported me in visiting Dr. Georgia Kapitsaki at the University of Cyprus (UCY) in Nicosia for a full month to work on this idea. Dr. Kapitsaki’s has already supported us in our work on Docear’s recommender system in July 2013. Her knowledge about the inner mechanics and her ideas on the the search engine were essential for the implementation and the research part of the project.

How to use it

You can access the search feature from Docear’s ribbon bar (“Search and Filter > Documents > Online search”) or by double-clicking the “Online search” entry in Docear’s workspace panel. Since both the recommender system and the personalized search engine make use of your mind maps. you need to enable the recommendation service in Docear.

Screenshot from 2014-07-07 15:19:39

After opening the search page, you will see

  • a text box for your search query,
  • a “Search” button, and
  • several buttons below the text box reflecting search terms you might be interested in. If Docear does not have enough data to decide about your interests, this part remains empty.

Docear-online-search-interface

(more…)

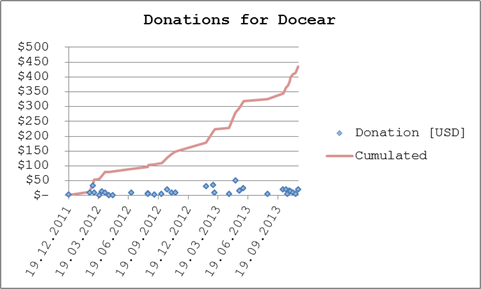
Docear’s users donate $434 in two years (i.e. ~4 Cent per user)

As you probably know, Docear is free and open source. As you might know as well, we do accept donations. Today, we would like to share some statistics with you about the amount of donations we received. Actually, in the past two years, we received 434 US$ (~340€) from from 33 donators. That’s not a lot, given that Docear has several thousands of active users. However, it’s also no surprise and to be honest, we ourselves hardly ever donate for other software tools, so we cannot blame anyone for not donating to Docear (even if he should heavily use it).

The average donation we received was 13.16$ (median was 10$), the highest donation was 50$, the smallest 1$, standard deviation 11.04$. The following chart shows the individual and cumulated donations. Sometimes, we don’t receive any recommendations for several month, sometimes we get multiple ones within a week or so.

(more…)

On the popularity of reference managers, and their rise and fall

This weekend, I had some spare time and I wondered which was the most popular reference manager (and how Docear is doing in comparison). So, I took a list of reference managers from Wikipedia, and checked some statistics on Alexa, Google Trends, and Google Keyword Planner. Since I had the data anyway, I thought I share it with you :-). Please note that this is a quick and dirty analysis. I cannot guarantee that there is not one or two reference managers missing (i just took the list from Wikipedia), and, of course, there are many alternatives to Alexa and Google for measuring the popularity of a reference manager.

(more…)